Ulam ranks Mistral Large 4 seventh on STEMBench
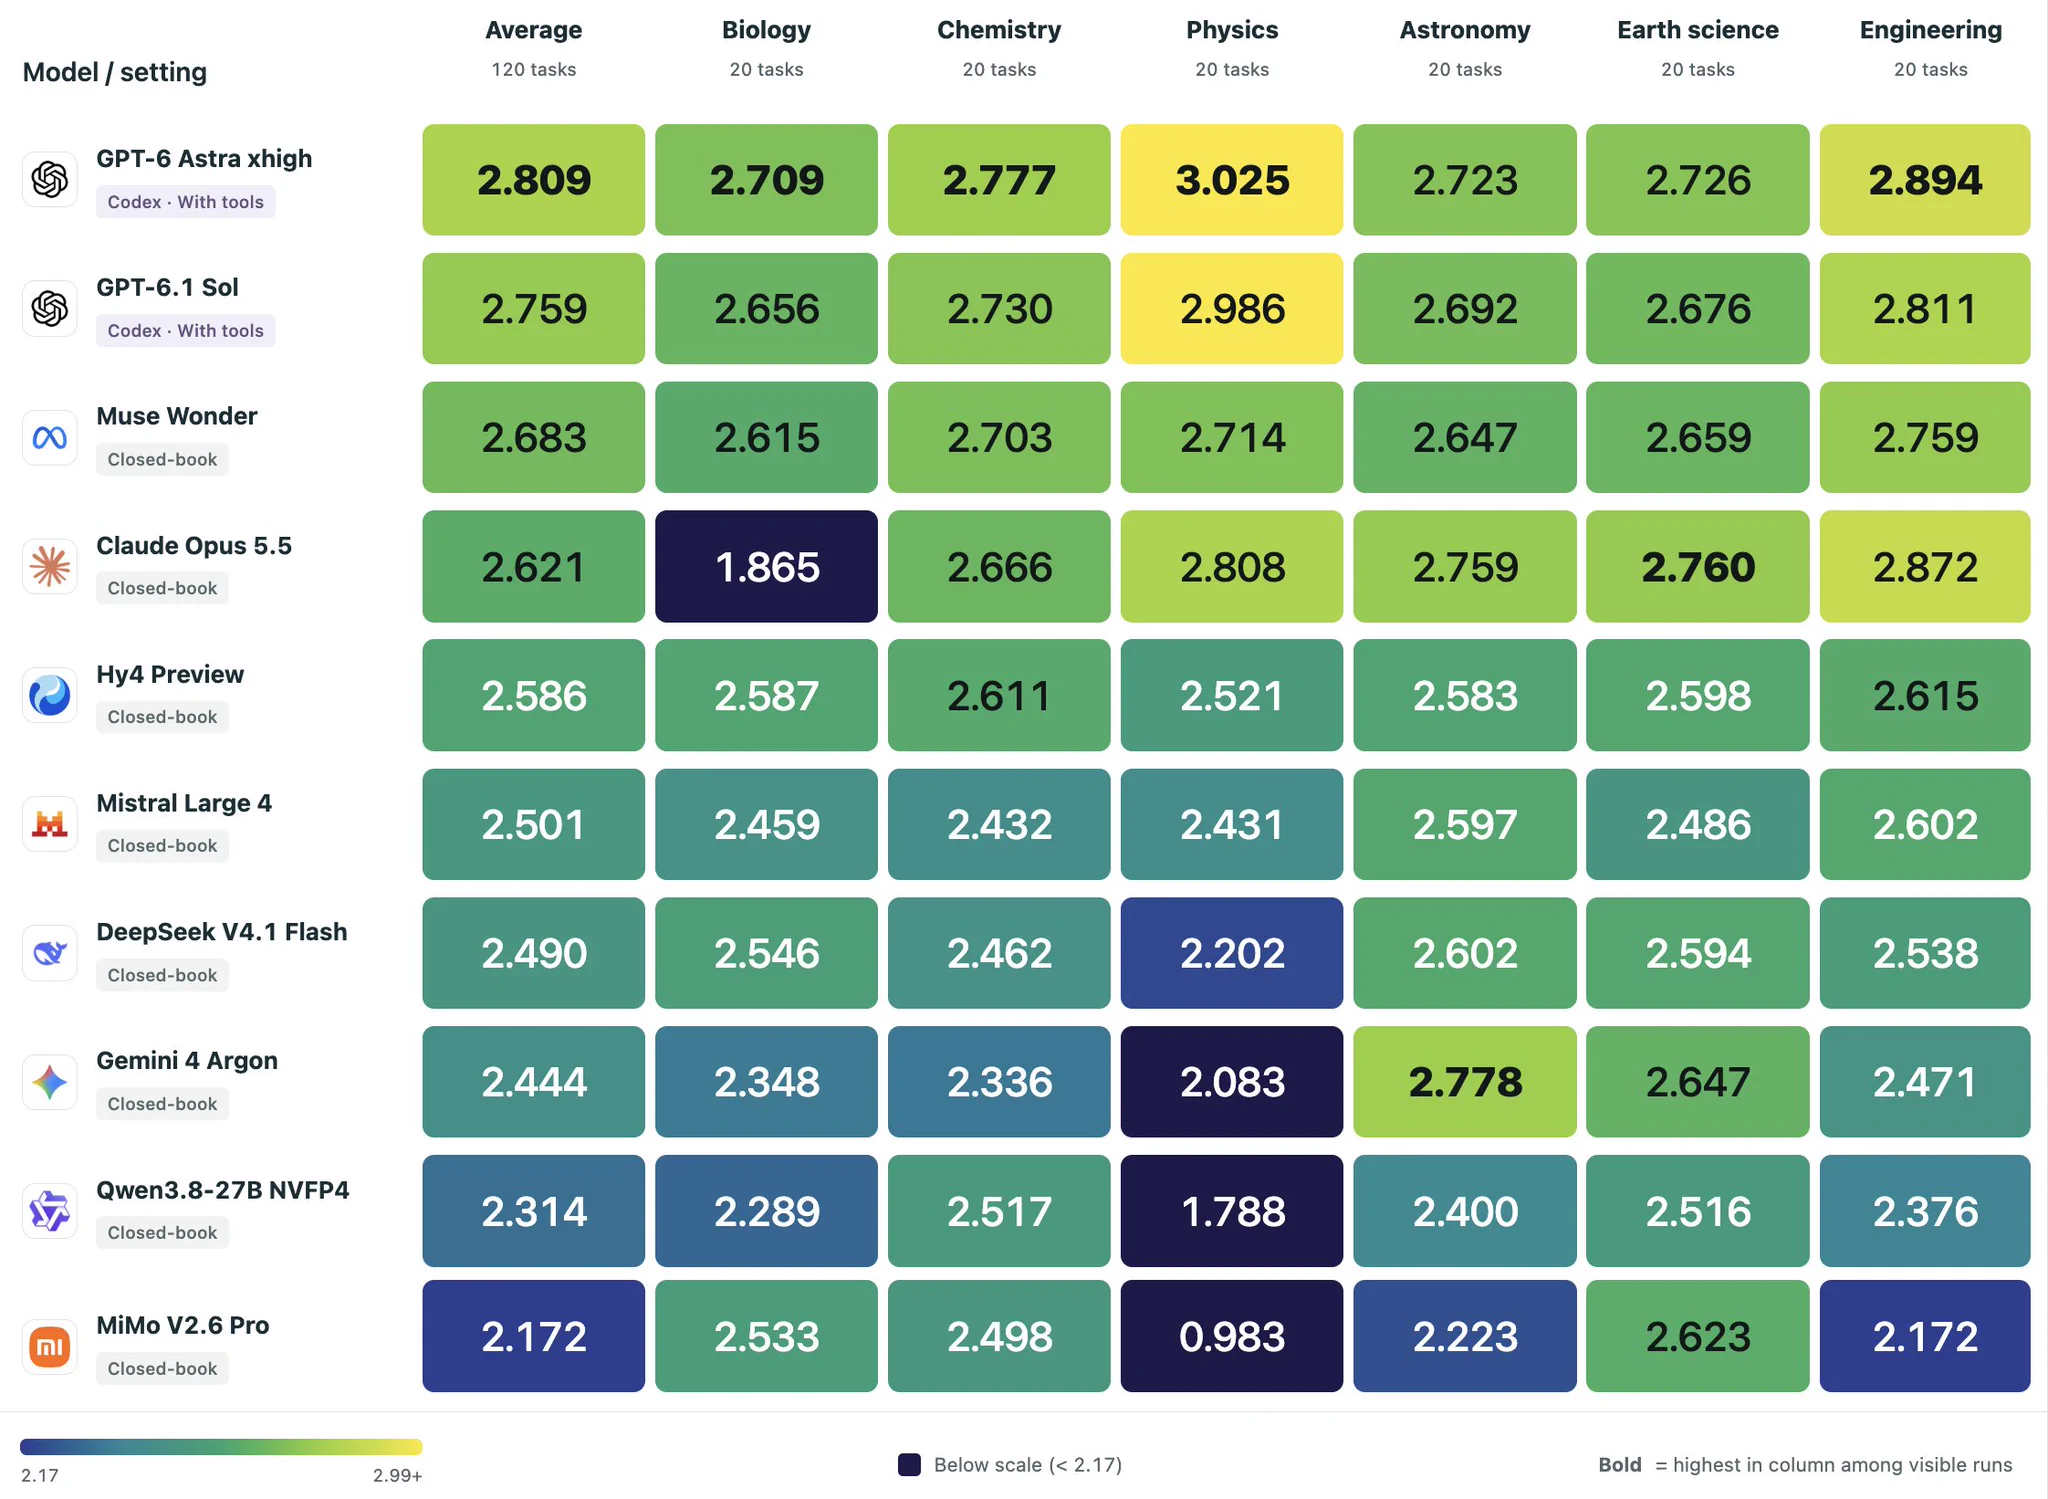
Ulam’s Oct. 28 audit snapshot lists Mistral Large 4 seventh on STEMBench, with a score of 2.501. Ulam identifies engineering and astronomy as the model’s strongest domains in the run.
Key takeaways · 4
- 01
The Oct. 28 snapshot lists Mistral Large 4 at rank seven with a 2.501 result.
- 02
Ulam names engineering and astronomy as the model’s strongest domains in the run.
- 03
The closed-book run had 111 level-2 results, seven level-1 results and no level-3 or full-target results.
- 04
Ulam says fractional scores indicate progress, not a percentage of tasks solved or a probability of correctness.
What the snapshot says
Ulam’s STEMBench120 page labels its audit snapshot Oct. 28, 2026, and lists Mistral Large 4 with a result of 2.501 and a rank of seven.[2] Ulam identifies engineering and astronomy as the model’s strongest domains in the run.[2] The benchmark lists biology, chemistry, physics, astronomy, Earth science and engineering as its six domains.[2] Its full run covers 120 research tasks, with 20 tasks in each domain.[3]
How to read the result
Ulam says STEMBench’s fractional scores describe progress, not a percentage of tasks solved or a probability that an answer is correct.[2] The 2.501 result should therefore be read as a benchmark score, not as a claim that the model solved a corresponding share of tasks.[2] Ulam describes the work as research tasks, and the result is tied to a run covering 120 tasks.[3][2] The snapshot does not, in the supplied information, provide task-level judgments or submissions for public comparison.[2]
What happened during the run
Ulam lists Mistral Large 4’s STEMBench run as closed-book.[2] Of its 120 scored attempts, 118 contained solver-authored content and two repeated the input.[2] Ulam reports 111 level-2 results and seven level-1 results, with no level-3 or full-target results for the model.[2] These counts describe the outcomes of this run; they do not establish that the model completed a full research target.[2]
Benchmark-wide caveat
Ulam reports that none of the 11 runs in the Oct. 28 snapshot met a full task target.[2] It also keeps STEMBench120 task statements, per-task judgments and model submissions out of the public comparison.[2] That means readers can compare the listed result and rank, but the supplied public comparison does not expose those underlying materials for independent task-by-task review.[2] The result is evidence about performance on this benchmark run, not a complete account of the model’s capabilities.[3][2]
For teams assessing AI for technical research, the score offers a structured comparison but not evidence that the model can complete a research task end to end. Treat it as one input to evaluation, alongside tests designed around your own work.
Why it matters
Bring this to your team — one session a day, built for your industry.
kju.ai is built for teams: daily sessions, team analytics, and rollout support for your organization.
For teamsHow this developed
3 November 2026
Ulam’s Oct. 28, 2026 audit snapshot lists Mistral Large 4 at rank seven with a score of 2.501, and adds run details including its closed-book setup and the distribution of scored attempts.
30 October 2026
Mistral Large 4 scores on Ulam’s STEMBench
Sources
- Mistral AI on X: \"Turns out le Chonk is into rocket science. Mistral Large 4 scoring well in engineering and astronomy on Ulam’s private benchmark, STEMBench: https://t.co/OW3reppzWN\" / Xx.com
- Introducing STEMBench - Ulam Blogulam.ai
- Mistral Large 4 on STEMBench: Strong in Engineering | AI Wireaiwirehq.com
- STEMBench — Six-Domain Model Evaluation | Ulamulam.ai
- Introducing Mistral Large 4 | Mistralmistral.ai