AWS and Cerebras Partner to Revolutionize AI Inference Speed on Amazon Bedrock
Amazon Web Services has teamed up with Cerebras Systems to deploy a groundbreaking AI inference architecture that promises up to tenfold speed improvements in generating AI model outputs, transforming real-time applications across industries.
Key takeaways · 5
- 01
AWS and Cerebras introduce disaggregated inference architecture to accelerate AI responses.
- 02
Cerebras’ wafer-scale WSE-3 chip offers 900,000 cores and 27 PB/s on-chip memory bandwidth, dwarfing traditional GPUs.
- 03
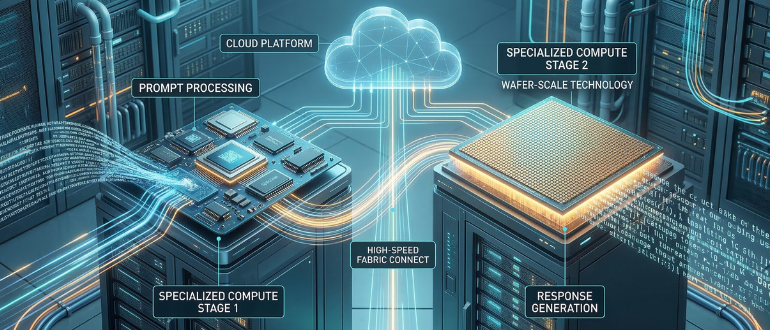
Prefill stage runs on AWS Trainium processors; decode stage runs on Cerebras WSE-3 chip, optimizing for distinct workload needs.
- 04
Integration into Amazon Bedrock enables developers to access faster inference with no code changes.
- 05
Expected launch in H2 2026 with capabilities benefiting enterprises deploying AI agents, real-time voice AI, and agentic workflow automation.
AWS has partnered with AI chipmaker Cerebras to deliver an unprecedented inference speed boost by integrating Cerebras’ wafer-scale WSE-3 chips within Amazon Bedrock’s managed infrastructure. This collaboration represents the first hyperscaler deployment of wafer-scale AI chips in the cloud.
Disaggregated inference splits the AI model inference process into 'prefill' and 'decode' stages, assigning each to a processor optimized for its workload. AWS's Trainium chips manage the parallel, compute-intensive prefill, while Cerebras’s WSE-3 chip handles the sequential, memory-intensive decode phase, significantly reducing inference latency.
Unlike traditional GPUs composed of multiple small chips, Cerebras designs a single monolithic wafer-scale chip integrating 900,000 AI cores and 44 GB of on-chip SRAM. With 27 petabytes per second of memory bandwidth, WSE-3 outperforms GPUs by a large margin, enabling rapid token generation that exceeds 3,000 tokens per second.
The enhanced inference speed directly benefits workloads such as real-time AI coding assistants, conversational agents, and voice AI, where low latency is critical. Faster inference translates into better user experiences, increased productivity, and new possibilities for agentic automation.
The AWS-Cerebras partnership signals a significant advance in AI inference infrastructure, addressing critical latency bottlenecks in deploying large language models at scale. By leveraging specialized hardware for distinct inference phases, it enables enterprises to run AI applications faster and more efficiently, enhancing user experience and opening new frontiers in real-time AI. This development could reset industry performance standards and influence future cloud AI hardware strategies.
Why it matters
Put this to work — one session a day, built for your industry.
Create a free account for a daily session — eight questions and one real-work challenge, on the news that affects your role.
Start freeSources
- AWS + Cerebras: 10x Faster AI Inference on Bedrock | AI Automation Globalaiautomationglobal.com
- AWS Inks Cerebras Deal for 5X Faster Cloud AI Inference Based With Its Trainium AI Chips - NewsBreaknewsbreak.com
- AWS strikes inference chip deal with Cerebras - NewsBreaknewsbreak.com
- AWS and Cerebras Team Up to Accelerate AI Inference in the Cloud - Techstrong ITzpr.io
- AWS and Cerebras Partner on AI Inference Speed and Cloudciofirst.com
- AWS and Cerebras partner to advance AI inference performanceverdict.co.uk
- AWS and Cerebras Team Up to Accelerate AI Inference in the Cloud - Techstrong ITtechstrong.it
- AWS and Cerebras Partner for Faster LLM Inferencetechedgeai.com
- AWS & Cerebras to Accelerate AI Inference Performance in Clouditdigest.com
- AWS and Cerebras Partner to Deliver Fastest AI Inference on Bedrock - Daily AI Briefdailyaibrief.com
- AWS Partners With Cerebras to Deliver Faster AI Inference on Amazon Bedrockmartechai.com
- OpenAI's Rapid Model Sprint, Cerebras Hits AWS, and Compute ...mlq.ai
- Cerebras is coming to AWScerebras.ai
- AWS and Cerebras collaborate on faster AI inference for Amazon ...digitimes.com